

- AI tools
- Artificial Intelligence
What Is Jev? TypeSafe AI's System One Model Explained
Jev is a new kind of AI model built to return fast, typed decisions instead of prose. Here is how System One works, what it costs, where it fits, and what its early evidence does—and does not—prove.
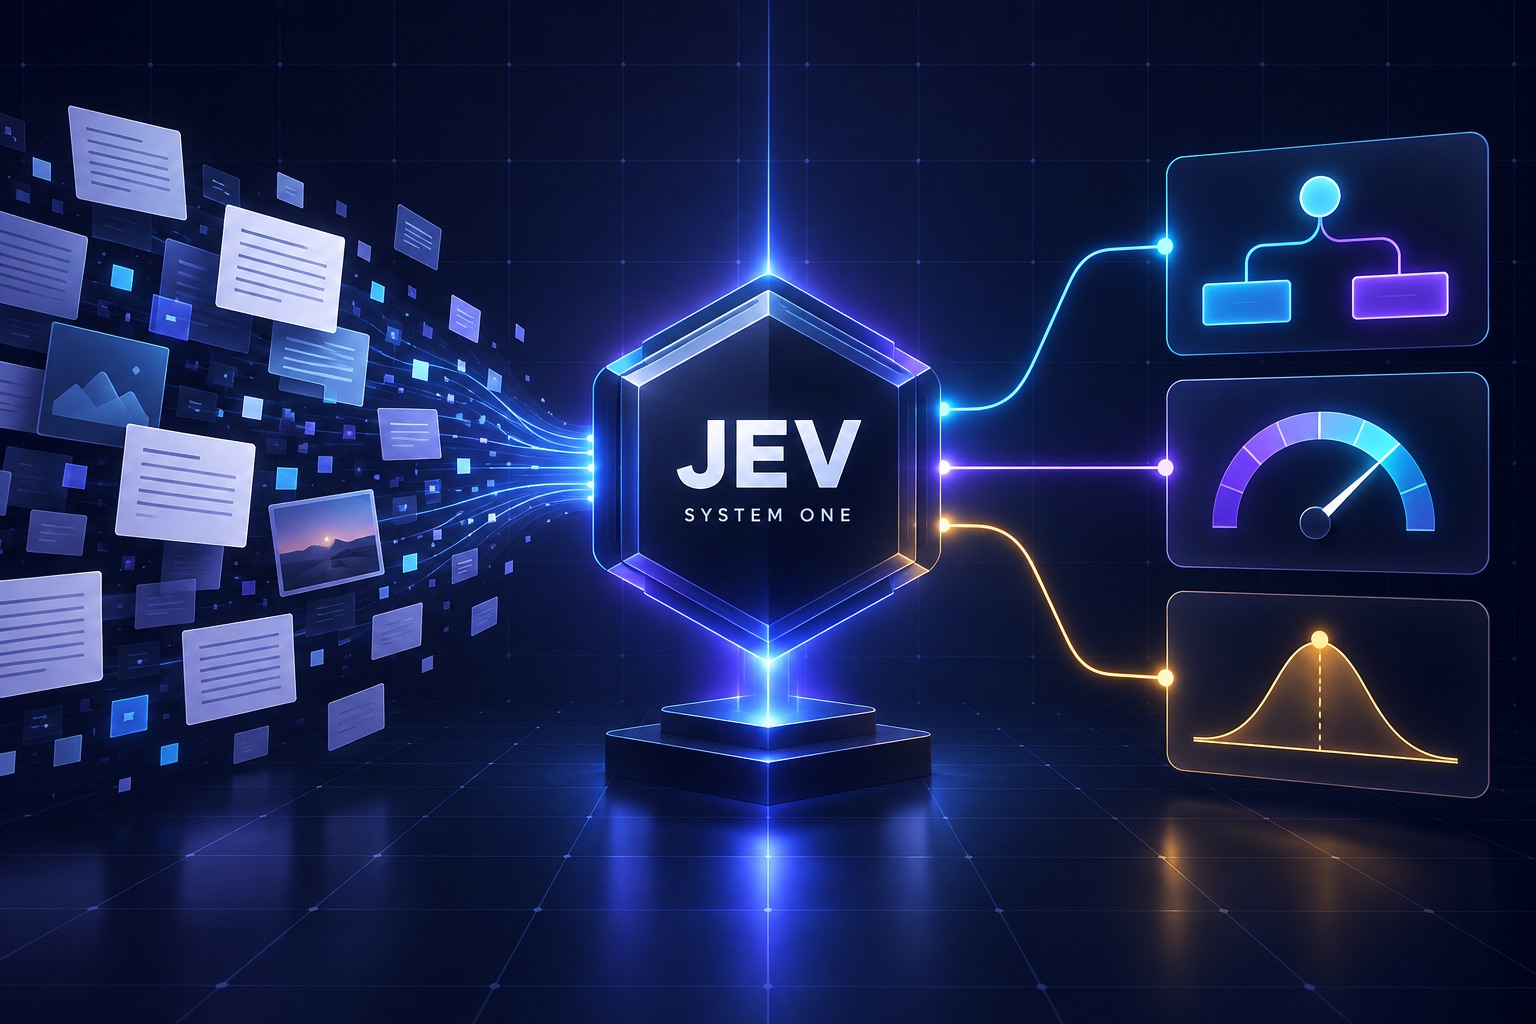
Most AI models are built to say something. Jev is built to decide something—and return the answer in a form software can use immediately.
A customer message arrives. Is it billing, support, or sales? A retrieved passage looks relevant. Is it strong enough to send to the answer model? An agent proposes an action. Should the workflow allow it, block it, or ask a person?
These are not really writing tasks. They are small judgments buried inside software. Teams often give them to a general-purpose language model because that is the AI tool they already have. The model reads the input, generates a response one token at a time, and the application parses the answer back into a label, score, or boolean.
TypeSafe AI introduced Jev on September 15, 2026 as a different kind of model. The company calls the category System One Models: unstructured state goes in, while bounded choices, scores, probabilities, and confidence come out. Jev does not chat, explain, or write code. It makes narrow semantic decisions.
That sounds like a small distinction. It may be an important one. If Jev's early speed, cost, and calibration claims survive broader testing, applications could stop using a large language model for every tiny branch in a workflow. The result would not replace an LLM. It would give the LLM—and the rest of the software around it—a faster decision layer.
This guide explains what Jev is, what “System One” means, how its Choice, Score, and Noul questions work, how much it costs, what the benchmark evidence shows, and where its limitations matter. For the compact specifications and first-party sources, see the Jev 1.13 model page or browse the new AI decision models category.
Quick answer — checked September 17, 2026
Jev 1.13 is TypeSafe AI's first System One model. It accepts text, JSON, or arrays of text plus predefined questions, then returns typed decisions with probabilities. TypeSafe lists it at $0.042 per million input tokens with free output and reports typical end-to-end latency of 70–500 milliseconds for suitable tasks. It is in early access. Those are provider-published figures, not universal guarantees.
| Jev fact | Current detail |
|---|---|
| Developer | TypeSafe AI |
| Current model | Jev 1.13; API ID jev-1.13.0 |
| Release | September 15, 2026 |
| What it returns | Choices, ordinal scores, probabilities, and confidence signals |
| What it does not return | Open-ended prose, explanations, code, images, audio, or video |
| Input capacity | 64K tokens per request; state plus the longest question up to 32K |
| Price | $0.042 per million input tokens; output is free |
| Published speed | 70–500 ms end to end for System One-shaped queries |
| Access | Early-access Playground and API with Python and JavaScript SDKs |
What is Jev AI?
Jev is a specialist model for making bounded judgments over text or structured state. Instead of prompting it to “write a JSON object” and hoping the generated response follows the format, a developer defines the possible answer before inference. Jev then returns one of those allowed values—or a score or probability—together with information about uncertainty.
The easiest mental model is a very capable classifier that can understand natural language, consider many questions at once, and expose how certain it is. That description is more useful than treating Jev as a tiny chatbot. It is designed to sit inside an application, not to be the application.
The Jev pattern
Unstructured state → Jev → Choice + score + probability → application code
The model handles the semantic judgment. Code still controls the rule, threshold, side effect, audit trail, and fallback.
Suppose a support system receives: “I upgraded yesterday, but my card was charged twice and the extra payment still has not disappeared.” One Jev request could ask whether the message concerns billing, how urgent it appears, whether it should be escalated, and how likely it is to contain sensitive account information. Each question has a declared output shape. The application can route the ticket without parsing a paragraph.
The current alias jev-latest resolves to jev-1.13.0. Most readers do not need to memorize that ID; it matters mainly for reproducible production tests. The broader idea is the product: Jev is the first member of a category TypeSafe hopes will handle the many tiny decisions surrounding agents, search, moderation, operations, and customer workflows.
Why call it a “System One” model?
The name borrows from the System 1 and System 2 framing popularized by psychologist Daniel Kahneman. System 1 describes fast, intuitive judgments; System 2 describes slower, deliberate reasoning. The analogy is not a claim that Jev thinks like a person. It describes the job the model is optimized to do.
A frontier LLM such as GPT-6 Astra or Claude Fable 5.1 is built for broad, generative work: investigate a problem, use tools, write code, explain tradeoffs, or produce a document. Jev is intentionally narrower. It reads the available state and returns a small decision quickly.
TypeSafe says the architecture uses a parallel sampler rather than generating an answer token by token. Its documentation also says questions in the same request are evaluated independently and in parallel. That means adding several classification or scoring questions should have a much smaller latency penalty than asking a general LLM to work through them sequentially.
The company trained Jev using RLCD, short for Reinforcement Learning for Calibrated Decisions. The important user-facing goal is calibration: across many similar predictions, an 80% probability should be right roughly 80% of the time. Calibration does not promise that an individual answer is correct. It makes the uncertainty more useful for routing and thresholds.
Choice, Score, and Noul: Jev's three question types
Jev currently exposes three primitives. Together they cover a large share of the small judgments hidden inside business software.
Choice selects from an allowed set
A Choice question gives Jev a fixed list of labels: billing, technical support, sales, cancellation, or something else. The response includes the selected label, the probability distribution across the available choices, and a confidence value derived from that distribution.
This fits intent classification, queue routing, policy selection, content tagging, and deciding which tool or agent should receive a task. TypeSafe documents support for up to 255 choices. For very large label sets, its own guidance is to narrow the field and then make a second decision instead of treating hundreds of near-duplicate choices as one flat problem.
Score places an item on an ordered scale
A Score question defines an ordered range—for example, urgency from one to five or lead quality from zero to ten. Jev returns a score along with the distribution over the allowed values and a confidence signal.
Scores are useful when the difference between adjacent outcomes matters. A risk score of four is closer to five than to one; a simple set of unrelated labels does not express that order. Applications can convert the result into service levels, review queues, thresholds, or prioritization.
Noul estimates the probability of a statement
A Noul question asks for a value between zero and one: how likely is this passage to answer the query, how likely is the request to violate a rule, or how likely is this agent trace to indicate a failure? Noul returns the probability directly. Unlike Choice and Score, the current Noul response does not add a separate confidence property.
The odd name is less important than the pattern. Instead of forcing a model to say “yes” or “no” at an arbitrary boundary, the application receives a probability and chooses the boundary itself. A harmless personalization decision might accept 0.65. A high-risk payment or security action might require 0.98 and a second check.
Does Jev really have “zero hallucinations”?
TypeSafe uses strong language around hallucination because Jev cannot invent a fourth category when the schema allows only three, return a paragraph where code expects a number, or improvise an unrecognized field. That is a meaningful reliability improvement. The shape of the response is bounded.
It does not mean the judgment is always true. Jev can still choose the wrong label, assign too high a score, misunderstand an indirect instruction, or become less reliable when the input is adversarial or full of irrelevant material. TypeSafe's own Jev 1.13 jaggedness guide documents those weaknesses.
A precise way to say it is:
- Schema hallucination is constrained. The output must fit the declared decision type.
- Semantic error is still possible. A valid label can still be the wrong label.
- Confidence helps manage error. It can trigger review or a fallback, but it is not proof.
This distinction matters for every structured AI system. JSON mode in a general LLM can guarantee parseable fields while the values inside those fields remain mistaken. Jev reduces the problem further by specializing the entire model around bounded decisions, but production teams still need evaluations and safe thresholds.
How fast and inexpensive is Jev?
TypeSafe's current model page lists Jev 1.13 at $42 per billion input tokens, equivalent to $0.042 per million input tokens. Output is free because Jev is not generating a long response. At that rate, one million 500-token classification requests would use 500 million input tokens and carry a model-list cost of about $21, before any application, storage, network, or human-review expenses.
The launch post reports 70 to 500 milliseconds end to end for tasks shaped for System One, and claims 40× to 200× speedups over the general models used in its comparisons. Those numbers need the context TypeSafe itself provides:
- most timing tests were run from laptops on the US West Coast;
- the four workflow evaluations were designed by the TypeSafe team;
- the comparison labels were derived from high-thinking GPT-6 Astra and Claude Fable 5.1 responses rather than independent human gold labels; and
- the company says early pricing may be subsidized and should not be assumed permanent.
In other words, the launch evidence is promising, not conclusive. The headline maximum—193.6× faster and 444.6× cheaper—is the favorable end of a set of vendor-run tasks, not a universal conversion factor for every LLM call.
What the early Jev evaluations actually show
TypeSafe publishes four workflow evaluations covering security-incident classification, agent-trace observability, invoice processing, and customer-service decisions. Each workflow decomposes one broad prompt into several typed questions, then compares accuracy, cost, and time with a general-model baseline.
The central result is less about a leaderboard than a workflow pattern. If a task ends in a handful of labels or numbers, a specialist model can avoid paying a general LLM to compose and serialize an answer it never needed to write. Parallel questions can also replace several separate calls.
There is one useful piece of outside evidence. Engineer Malte Ubl wrote that he ran Jev against an existing classifier evaluation that had used Gemini 2.5 Flash-Lite; in that one test, Jev saturated the quality evaluation and ran about six times faster. That report is encouraging because the evaluation predated Jev, but it is still a single developer's test—not a broad independent benchmark suite.
For a quick visual explanation, Matija Sosic published a 45-second Jev summary. Steve Krouse also shared a small live demo that makes the state-and-questions pattern easier to feel than a benchmark table.
The evidence is enough to justify testing Jev. It is not yet enough to declare that Jev beats every small LLM, classifier, reranker, or rules engine. A fair evaluation should use frozen examples from the actual product, human-reviewed labels, the same network path, and a threshold policy chosen before seeing the results.
Jev vs LLMs: what is actually different?
| Dimension | Jev / System One | General-purpose LLM |
|---|---|---|
| Main job | Choose, score, or estimate probability | Generate, reason, explain, code, and use tools |
| Output | Predefined typed values | Open-ended tokens, optionally constrained to JSON |
| Uncertainty | Native probability distributions and confidence where supported | Usually not exposed as a calibrated application signal |
| Multiple questions | Independent questions evaluated in parallel | Often answered in one generated sequence or several calls |
| Best at | High-volume, narrow semantic decisions | Ambiguous, creative, multi-step, or explanatory work |
| Cannot do | Write prose, code, or explanations | Can generate all three |
The right comparison is therefore not “Can Jev beat a frontier model?” It is “Why are we asking a frontier model to do this particular job?” A small general model such as GPT-5.6 Luna or Claude Haiku 4.5 remains more flexible. It can extract a field, rewrite a message, call a tool, and explain its answer in the same request. Jev gives up that flexibility in exchange for a tighter contract.
Jev vs structured output or JSON mode
Structured output is the closest familiar alternative. A developer gives an LLM a schema; the provider constrains the generated response so it parses. This is excellent when an application needs a rich object with names, descriptions, dates, or other generated fields.
Jev is better matched to a smaller output space. The answers already exist; the model only selects or scores them. There is less output to generate, the probability distribution is part of the product, and the whole architecture is optimized around the decision. Use JSON mode when you need generated content inside a structure. Consider Jev when every valid answer is already known.
Jev vs a traditional classifier
A conventional classifier can be extremely fast and inexpensive after training. It may be the best choice for a stable, high-volume problem with enough labeled data. Jev's appeal is that it tries to bring natural-language flexibility and few-shot setup to that class of work without asking each team to train and operate a separate model.
The tradeoff is control. A custom classifier can be tuned around a narrow taxonomy, inspected with familiar metrics, and deployed in a private environment. Jev is currently a hosted early-access service. Teams should compare not only accuracy and latency, but also data location, retraining needs, label churn, and operating effort.
Jev vs a reranker
A reranker such as Cohere Rerank 4 Fast takes a query and candidate documents, then orders those candidates by relevance. Jev can ask whether a passage answers a question or score a passage against a rubric, but it is not automatically a drop-in reranking model with the same training objective and search-specific contract.
For RAG, the tools can complement one another. Retrieval finds candidates, a reranker orders them, and Jev can make a bounded decision such as “Is the top evidence sufficient to answer?” or “Which policy topic does this passage support?” A larger model then writes the cited answer only when the decision layer says the evidence is adequate.
Where Jev could be useful
1. Routing requests and agent work
Jev can classify an incoming request, select a specialist agent, score urgency, and decide whether a person must review it. Because each output is bounded, the orchestrator does not need to interpret a narrative answer before taking the next step.
2. Adding confidence gates to AI agents
An agent can propose an action while Jev separately judges whether the action matches the user's goal, falls inside policy, or appears complete. Low-confidence cases can pause. This is not a complete security boundary—the model can still be influenced by adversarial input—but it can add a fast semantic check before code enforces the final rule.
3. Improving RAG and enterprise search
Document systems already use specialist layers: a parser such as Cohere Parse or the open-source tools in our Docling guide recover structure; embeddings retrieve candidates; rerankers reorder them. Jev could add another decision: whether the evidence is sufficient, contradictory, sensitive, outdated, or appropriate for a particular answer path.
4. Triage, scoring, and operations
Leads, support tickets, invoices, incident reports, reviews, and agent traces all contain unstructured language that eventually becomes a queue or a score. Jev is designed for that conversion. The value is highest when the taxonomy changes often enough to make a custom classifier inconvenient but the output remains bounded enough that prose is unnecessary.
5. Map-reduce decisions over many items
A workflow can apply the same question independently across passages, records, messages, or trace spans, then let code aggregate the results. This keeps the model focused on local semantic judgments while deterministic code handles counting, thresholds, and final selection.
Where Jev is not the right tool
TypeSafe is unusually direct about Jev's jagged edges. That transparency is useful because a specialist model can look broadly intelligent in one demo and fail on a neighboring task.
- Do not use it to write. Jev cannot draft a reply, explanation, summary, or line of code.
- Keep arithmetic in code. The provider documents weaknesses in counting, calculation, and numeric precision.
- Keep date logic in code. Comparing dates and times is a documented weak point.
- Write questions literally. Indirect or nested instructions can reduce reliability.
- Remove irrelevant context. Large amounts of unrelated state can hurt the decision even when they fit the context limit.
- Test adversarial input. Prompt injection and contradictory instructions can still steer the model.
- Do not confuse calibration with certainty. A high confidence value needs validation on the product's own data.
A good rule is to leave deterministic facts to deterministic systems. Code should calculate totals, compare timestamps, check permissions, enforce limits, and execute side effects. Jev should handle the piece that genuinely requires semantic judgment.
A practical architecture: use Jev beside an LLM
The most compelling design is a cascade rather than a replacement:
- Code performs hard checks. Validate authentication, limits, required fields, dates, and numeric rules.
- Jev makes the narrow semantic decision. Classify the request, score risk, or estimate whether the evidence is sufficient.
- The workflow reads uncertainty. Accept a confident low-risk decision, route an ambiguous case to a larger model, or ask a person.
- An LLM handles generative work. Write the reply, research the issue, call approved tools, or explain the result.
- Code owns the action. Log the decision and source version, enforce policy, and make the final state change.
This layout can reserve expensive reasoning for the cases that need it. It can also make an agent easier to audit: the decision record contains the question, allowed answers, probability, threshold, selected route, and model version instead of an opaque paragraph that another component interpreted.
How to evaluate Jev before using it in production
- Start with an existing decision. Choose a task that already ends in a label, ordered score, or probability—not a writing task squeezed into a classification demo.
- Freeze a representative test set. Include easy cases, ambiguous cases, rare labels, long inputs, contradictory language, and adversarial examples.
- Use human-reviewed labels. An LLM consensus can bootstrap exploration, but production accuracy should be measured against a standard people have approved.
- Measure calibration, not only accuracy. Group predictions by probability and check whether confidence matches observed correctness.
- Set thresholds by consequence. Optimize the false-positive and false-negative tradeoff for the actual decision. A marketing tag and a payment hold should not share a threshold.
- Compare full task cost. Include retries, fallback LLM calls, human reviews, networking, and engineering—not only token price.
- Pin the model version. Use
jev-1.13.0for a reproducible evaluation; move tojev-latestonly with regression tests. - Log safely. Record enough to debug the decision without retaining sensitive source text longer than necessary.
Jev API access in plain English
Jev is available through TypeSafe's early-access API and Playground. The API uses POST /v1/systemone, and TypeSafe provides Python and JavaScript SDKs. A request contains the shared state plus one or more questions. The response contains the typed results.
The current published early-access limits are 250,000 input tokens per second and 1,200 requests per minute, although TypeSafe says limits are dynamic while demand settles. One request can contain several independent questions, so a workflow may not need one network call for every decision.
Developers should keep two aliases in mind. jev-latest follows the stable production line and currently points to Jev 1.13. jev-preview is intended for the newest candidate and currently points to the same version. Pin the numeric ID when a change in behavior would affect a regulated or high-impact workflow.
Privacy and enterprise considerations
TypeSafe's privacy policy says customer input is not used to train or fine-tune its models. It also says the services are hosted in the United States. The public policy does not promise one fixed zero-retention period for every API request; it describes retaining personal information as reasonably necessary for the stated purposes.
That is not the same as saying Jev is unsuitable for enterprise data. It means buyers should obtain the exact data-processing, retention, subprocessors, deletion, security, and regional terms their workload requires. Early access is also the right time to ask about service-level commitments, audit logs, model-version notices, incident response, and capacity guarantees.
Frequently asked questions
What is Jev?
Jev is TypeSafe AI's first System One model. It turns text or structured state into predefined choices, scores, and probabilities for application code instead of generating open-ended prose.
Is Jev an LLM?
TypeSafe presents Jev as a new specialist model category rather than a general-purpose LLM. It understands natural-language state, but its job is bounded decision-making, not token-by-token text generation.
How much does Jev cost?
TypeSafe currently lists Jev 1.13 at $0.042 per million input tokens, with no output-token charge. The company says early pricing may be subsidized, so production buyers should verify the live rate.
How fast is Jev?
TypeSafe reports 70–500 ms end-to-end latency for suitable System One queries. That is a provider-reported range, not a universal SLA, and geography, load, input length, and workflow design can change the result.
What are Choice, Score, and Noul?
Choice selects from predefined labels, Score chooses a value on an ordered scale, and Noul returns a probability between zero and one. Choice and Score also return distributions and a confidence value; Noul returns the probability itself.
Can Jev hallucinate?
Jev cannot invent an output outside the declared type, which prevents malformed or open-ended responses. It can still make a semantically wrong decision, so teams must evaluate accuracy, calibration, adversarial behavior, and thresholds.
Can Jev replace GPT or Claude?
No. Jev does not write, explain, code, browse, or operate tools. It can replace some narrow classification or scoring calls and can route difficult cases to a general model such as GPT or Claude.
Is Jev good for RAG?
Potentially, as a decision layer. Jev can judge whether evidence is sufficient, classify passages, score policy relevance, or gate an answer. It does not create embeddings, parse documents, rerank candidates by default, or write the final cited response.
Is Jev generally available?
No. Jev is in early access through TypeSafe's Playground and API as of September 17, 2026.
Sources and methodology
This article was researched on September 17, 2026. Product design, speed, cost, and benchmark claims come from TypeSafe AI's launch article, System One documentation, model and pricing page, confidence guide, quickstart, and workflow evaluation site. Limitations come from the provider's Jev 1.13 jaggedness guide; data-handling statements come from its privacy policy.
We label provider-run results as provider claims. Malte Ubl's classifier result is included as one independent practitioner report, not as a universal benchmark. We did not run Jev ourselves, and we do not convert TypeSafe's highest speed or cost multiplier into a claim about unrelated workloads. Prices, aliases, access, and early limits can change after publication.
The bottom line
Jev is interesting because it questions a habit that has become normal in AI software: sending every semantic task to a model built to write. Many production decisions do not need an essay. They need a known label, an ordered score, or a probability that code can act on.
TypeSafe's first release makes an ambitious case for that specialist layer. The price is tiny, the reported latency is measured in milliseconds, the output contract is narrow, and uncertainty is available to the application. The launch evaluations and early developer test make Jev worth serious experimentation.
The limits are part of the idea, not an afterthought. Jev cannot explain itself, should not do arithmetic or date logic, can still misclassify, and remains vulnerable to poor context and adversarial instructions. It belongs between deterministic code and a general-purpose LLM—not above both.
If that architecture holds up on real data, “System One model” could become a useful category. Jev does not need to replace GPT, Claude, or a trained classifier to matter. It only needs to handle enough of the small decisions around them faster, more cheaply, and with a cleaner contract.